The content existed. The system around it did not
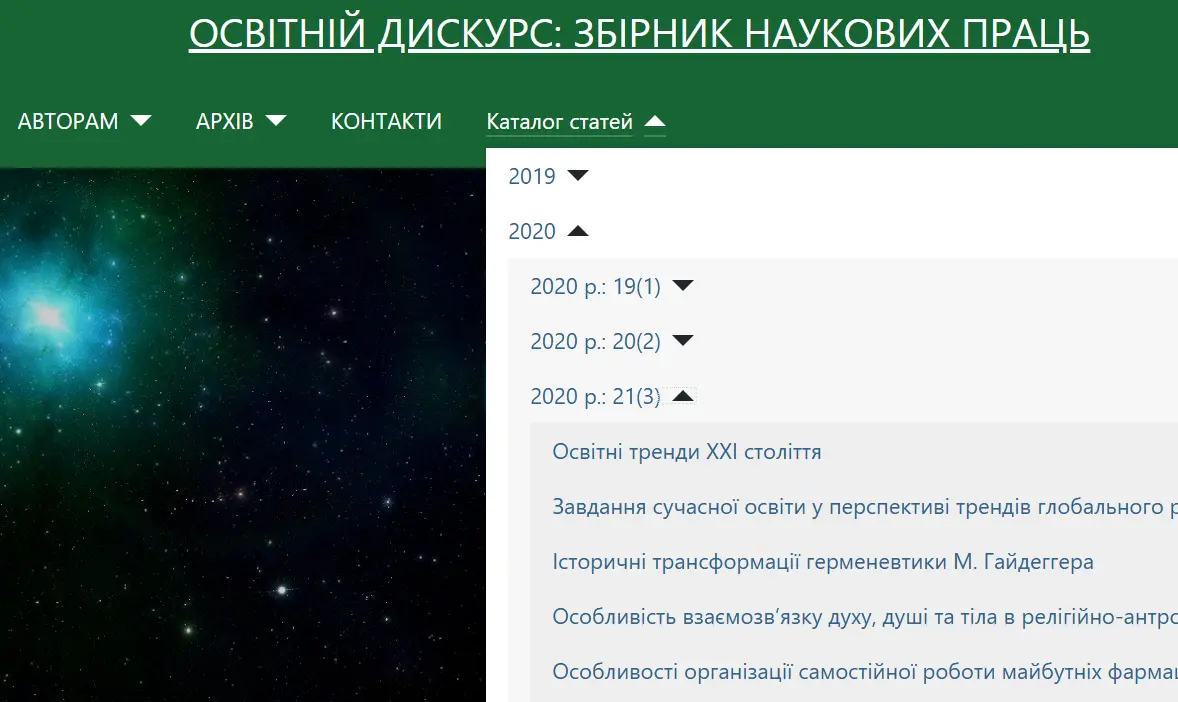
The legacy website could not be migrated as a set of pages. Publication data had been added inconsistently over the years, without a shared structure.
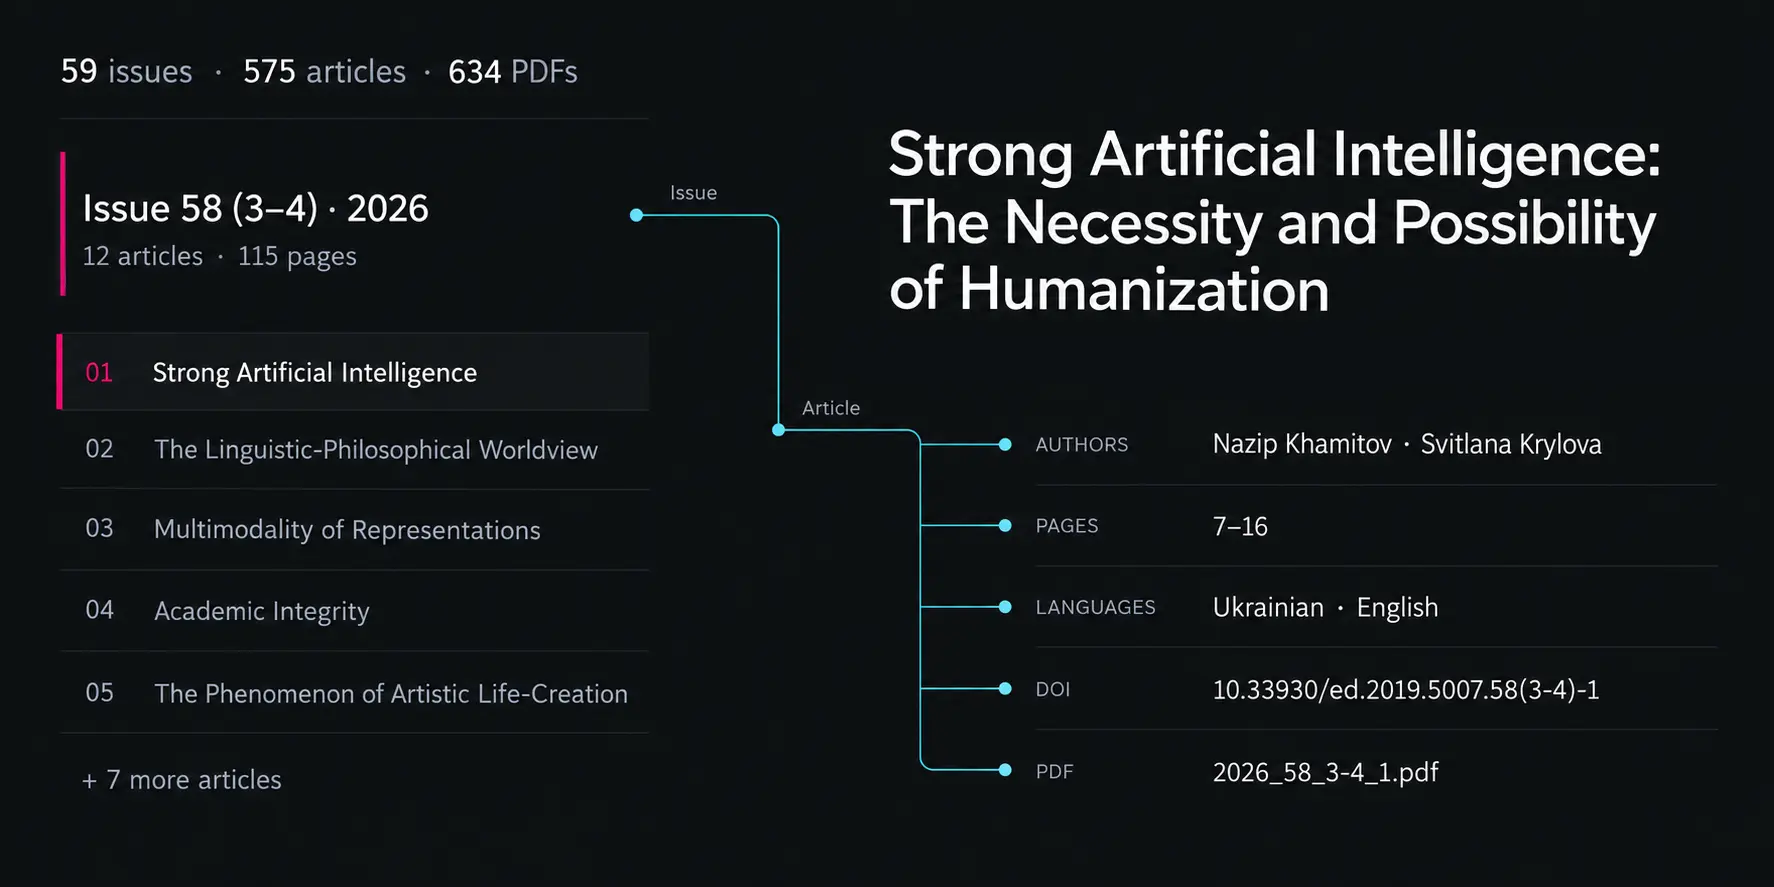
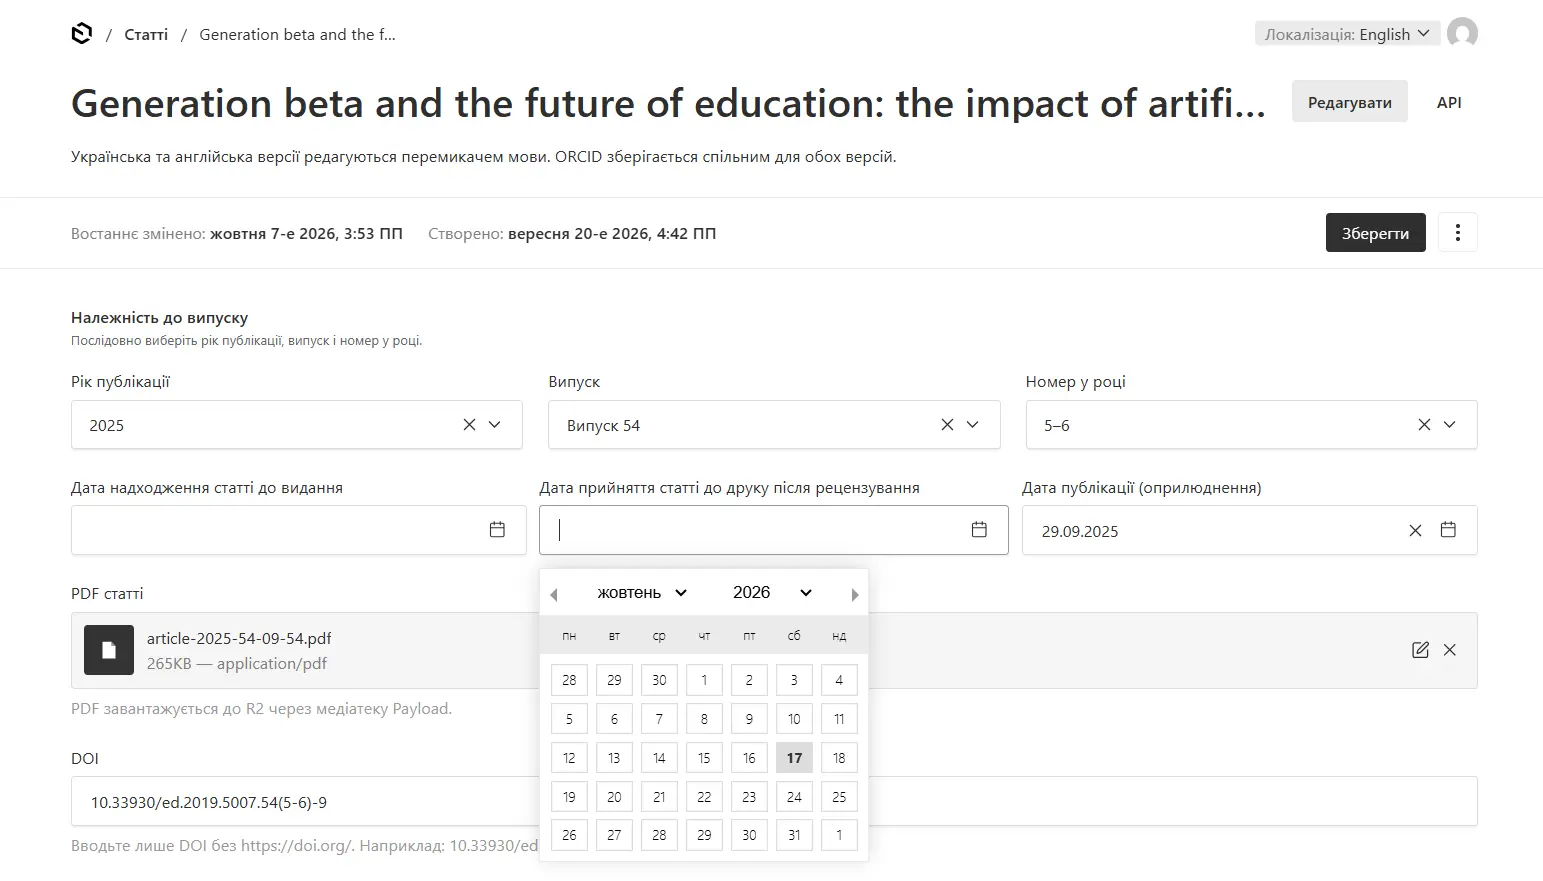
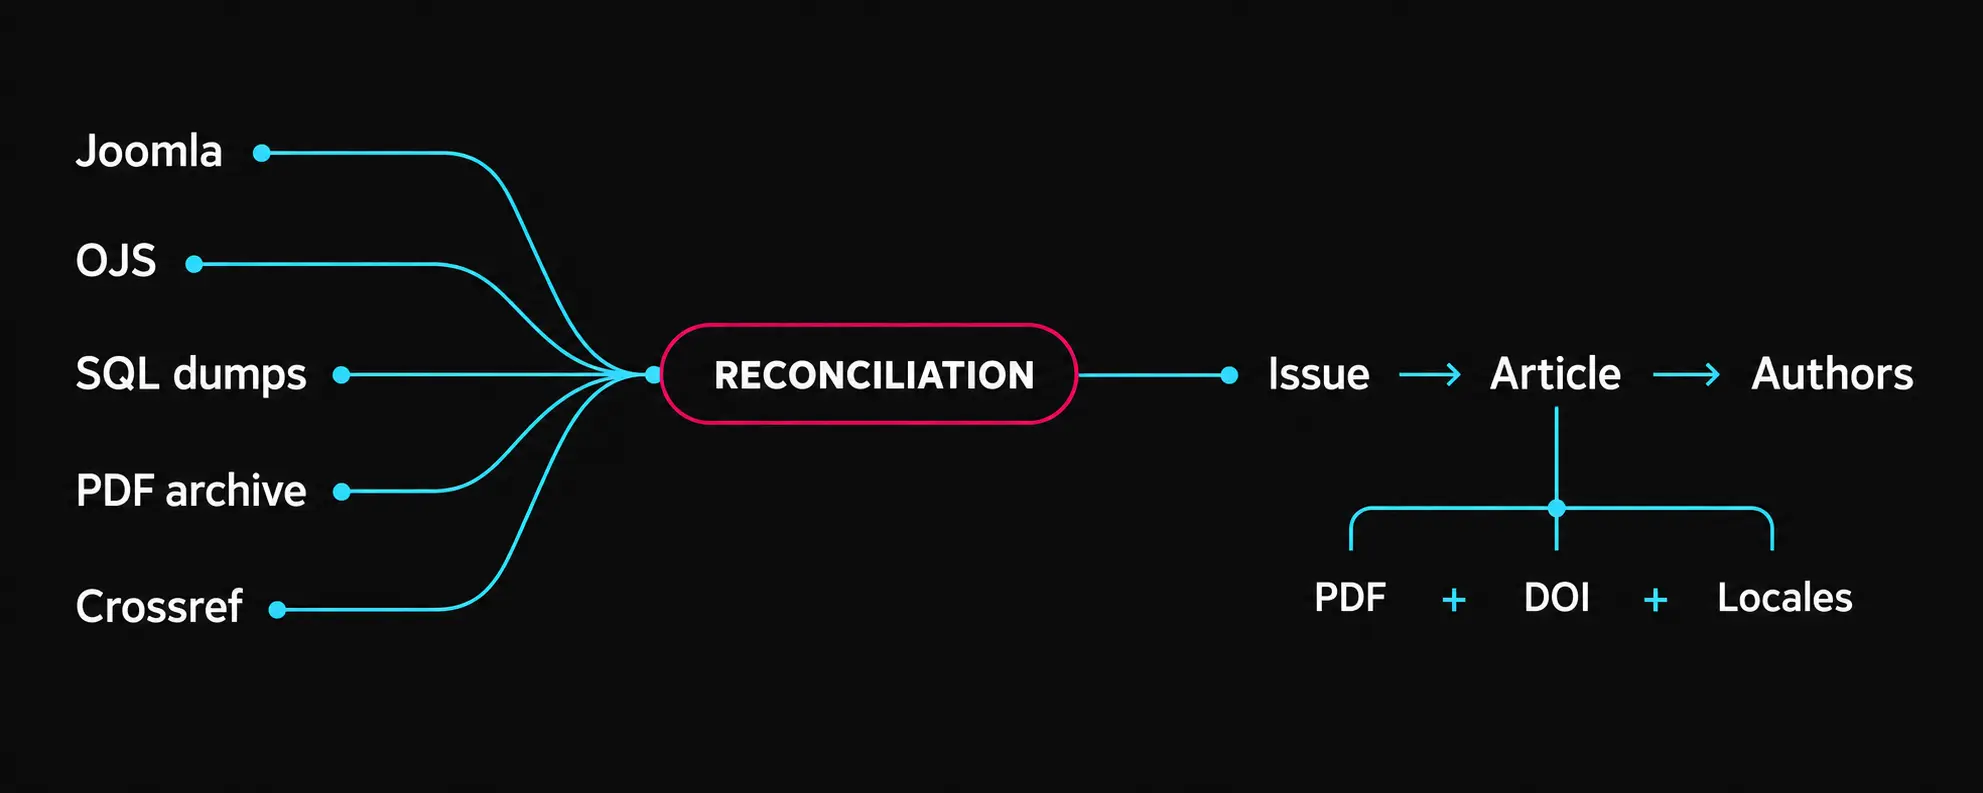
We reconstructed the archive by cross-checking every issue and article against databases, PDF files, server files, and Crossref records, identifying and completing missing records and fields, and restoring the correct relationships.
- No consistent issue structure
- Different naming conventions
- Articles disconnected from issues
- Files stored separately from metadata
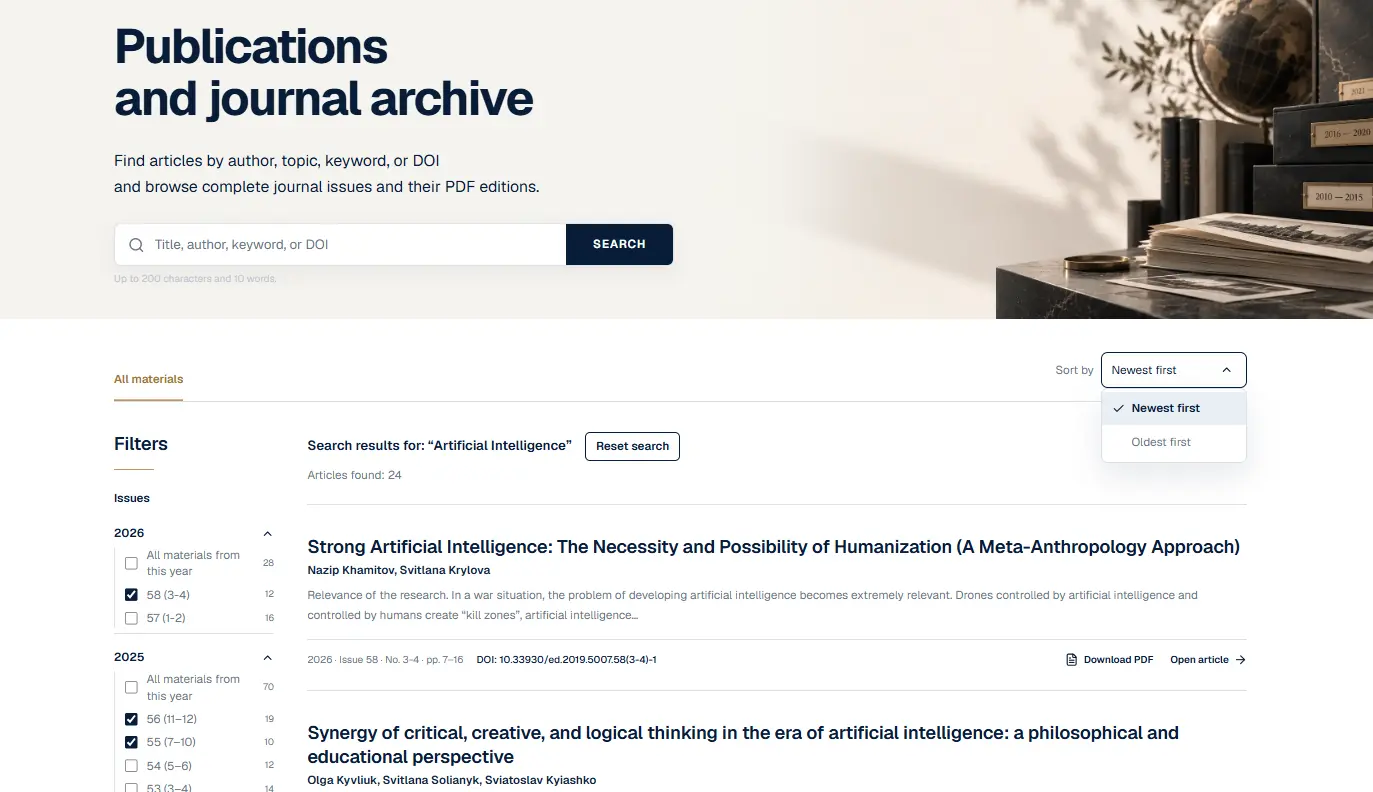
- No reliable archive search
- Legacy URLs embedded in external records
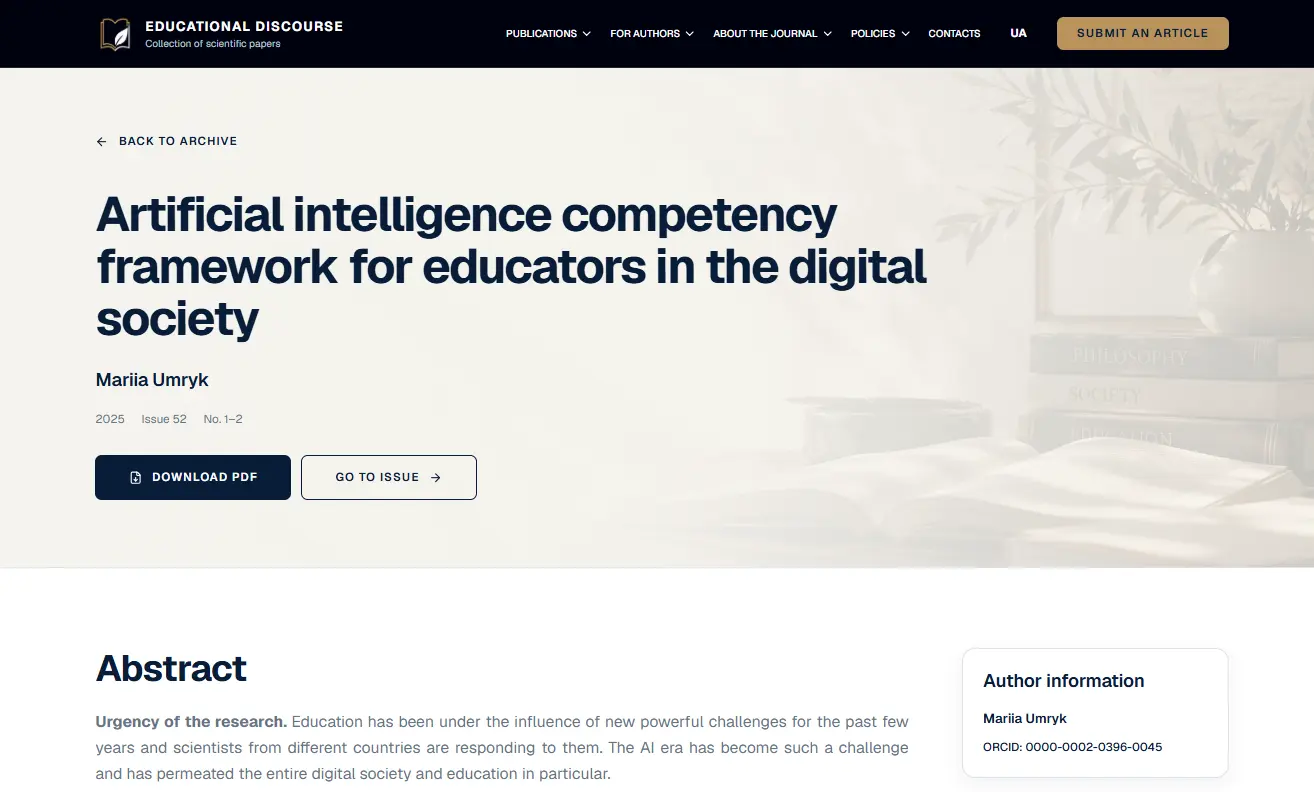
This work turned disconnected source material into a consistent publication model.